Pegasus 1.6 brings video understanding to physical AI, says TwelveLabs
TwelveLabs upgrades its video foundation model to streamline robot training through sophisticated visual intelligence.
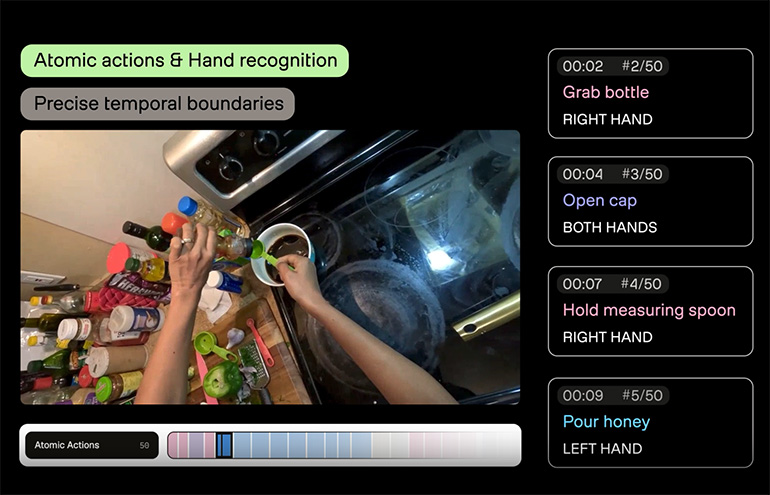
TwelveLabs says its Pegasus 1.6 model understands first-person video and supports workflows including labeling for robotics developers. The post Pegasus 1.6 brings video understanding to physical AI, says TwelveLabs appeared first on The Robot Report.
The Robot Report
Source
Generated insight by OnAirToday AI
Pegasus 1.6 represents a significant leap in multimodal AI by enabling robots to interpret visual sequences in real-time, bridging the gap between raw video data and actionable physical commands. This breakthrough effectively accelerates the training phase for autonomous systems, allowing them to learn complex tasks through observation rather than manual programming.

Comments
Keep comments relevant and respectful. No links, advertising, self-promotion, or spam.